
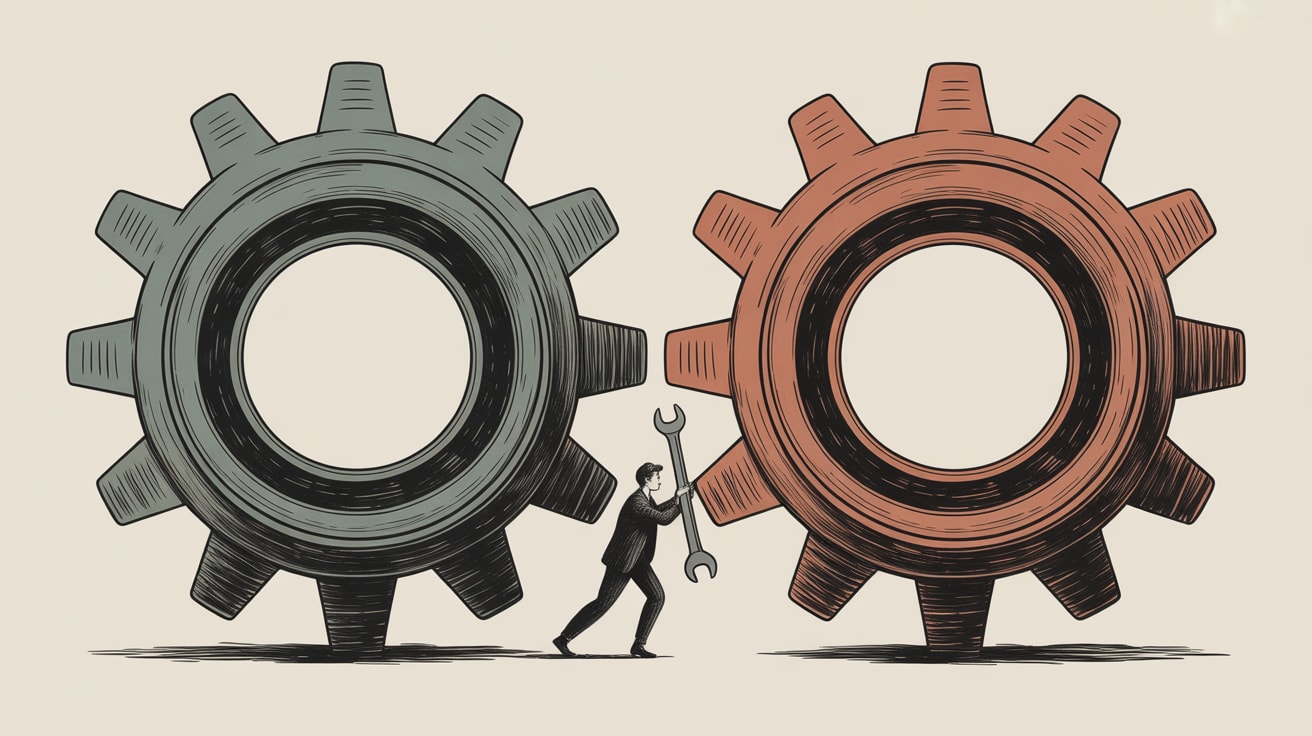
RAG retrieves. Agents act. But who owns the layer between them? Why this architectural gap matters for real-time customer engagement in Southeast Asia.
Most teams building AI into their customer engagement stack are quietly making the same architectural mistake. They’re treating retrieval and action as a single system — and then wondering why their “intelligent” engagement flows feel anything but.
The gap between RAG and agentic execution isn’t a minor plumbing detail. For customer engagement platforms operating in the real-time, multi-channel messiness of Southeast Asian markets, it’s the difference between a system that retrieves the right context and one that actually does something useful with it.
RAG Retrieves. Agents Act. Neither Does Both Well.
Emmimal P Alexander’s work at Towards Data Science makes a point that should be uncomfortable for anyone who’s shipped a “RAG-powered” engagement feature: RAG and agents are fundamentally different primitives, and conflating them produces systems that do neither job well. Alexander built both layers separately — retrieval and action — then connected them explicitly, running identical tasks through all three architectures. The retrieval-only system found relevant context. The agent-only system acted but often on stale or incorrect assumptions. Only the explicitly connected system consistently retrieved and acted correctly.
For a CEP context, this maps directly: a retrieval system can surface that a Shopee user abandoned a cart three hours ago and has a high reorder propensity. An agent can trigger a push notification or LINE message. But without an explicit orchestration layer deciding when retrieval output is sufficient evidence for a specific action — and what the fallback is when it isn’t — you’re just wiring two black boxes together and hoping for coherence.
The Orchestration Layer Nobody Wants to Build
The reason teams skip explicit orchestration is understandable: it’s unglamorous infrastructure work that doesn’t ship to a demo. But it carries real business cost. In high-frequency engagement scenarios — flash sale triggers, real-time abandonment recovery, dynamic offer personalisation across Grab, Lazada, and web simultaneously — a retrieval system that dumps context into an agent without structured handoff logic produces action latency, context loss between steps, and compounding errors that are nearly impossible to debug in production.
The fix isn’t sophisticated. Alexander’s approach was to define clear input/output contracts between layers: the retrieval layer returns structured, typed outputs; the orchestration layer applies decision logic to determine action eligibility; the agent layer executes within defined guardrails. This separation also makes the system auditable — a non-trivial concern in markets like Thailand and Indonesia where personalisation practices are drawing increasing regulatory attention.
The practical implication for engagement teams: before your next AI feature build, map which layer owns which decision. If that conversation is awkward, the architecture probably isn’t ready for production.
Graph-Based Context Makes the Retrieval Layer Actually Useful
Retrieval quality is the silent constraint most teams underestimate. A well-architected orchestration layer is only as good as the context it receives — and flat vector retrieval over customer event logs has a ceiling that becomes obvious fast in complex, multi-touchpoint journeys.
Partha Sarkar’s work on GraphRAG with TypeSafe Jev at Towards Data Science points toward a more durable architecture: using knowledge graphs to encode entity relationships (customer → segment → behaviour → product affinity → channel preference) alongside calibrated decision models that handle high-frequency graph traversal, while reserving LLM reasoning for synthesis and open-ended generation. The System One framing is apt — fast, pattern-matched decisions at graph query time, slow deliberate reasoning only where it adds value.
For Southeast Asian engagement contexts, this architecture addresses a specific pain point: multilingual, multi-platform customer journeys produce entity graphs that are genuinely complex. A single customer might interact via TikTok Shop in Thai, a LINE OA in English, and a brand’s native app in a code-switched mix of both. Flat retrieval over event logs misses the relational structure that makes personalisation contextually coherent. Graph-based retrieval preserves it.
Implementation note: TypeSafe schema enforcement on graph outputs is what makes the downstream orchestration layer tractable. Without typed outputs, the action layer inherits ambiguity — and ambiguity in high-velocity engagement flows produces either over-triggering or paralysis.
Closing the Loop: What This Means for CEP Architecture
Putting these two threads together produces a cleaner CEP architecture pattern than most teams currently run: a graph-enriched retrieval layer that returns typed, structured context; an explicit orchestration layer that applies deterministic decision logic to determine action eligibility and priority; and an agent layer that executes narrowly, within defined parameters, without needing to re-derive context.
This isn’t a novel idea in principle — it’s essentially what mature CEP vendors have been selling for years. The shift is that teams can now build this without vendor lock-in, using open components, provided they’re disciplined about the contracts between layers. The teams that will struggle are those that reach for an end-to-end LLM agent as a shortcut, discover it hallucinates action eligibility under load, and then spend three quarters trying to patch a fundamentally misaligned architecture.
The question worth sitting with: if your current engagement stack failed to correctly decide not to send a message — because the retrieval context said one thing and the action logic assumed another — would you know? And how quickly?
At grzzly, we work with marketing and data teams across Southeast Asia to architect CEP frameworks that hold up under real-world conditions — messy data, multi-platform journeys, and the kind of engagement velocity that exposes architectural shortcuts fast. If you’re rebuilding your activation layer or questioning whether your current setup can scale, we’d rather have that conversation early. Let’s talk
Sources
Written by
Brooding GrizzlyDesigning CEP frameworks that move beyond batch-and-blast into real-time, context-aware engagement — across channels, devices, and the messiness of actual human behaviour.