
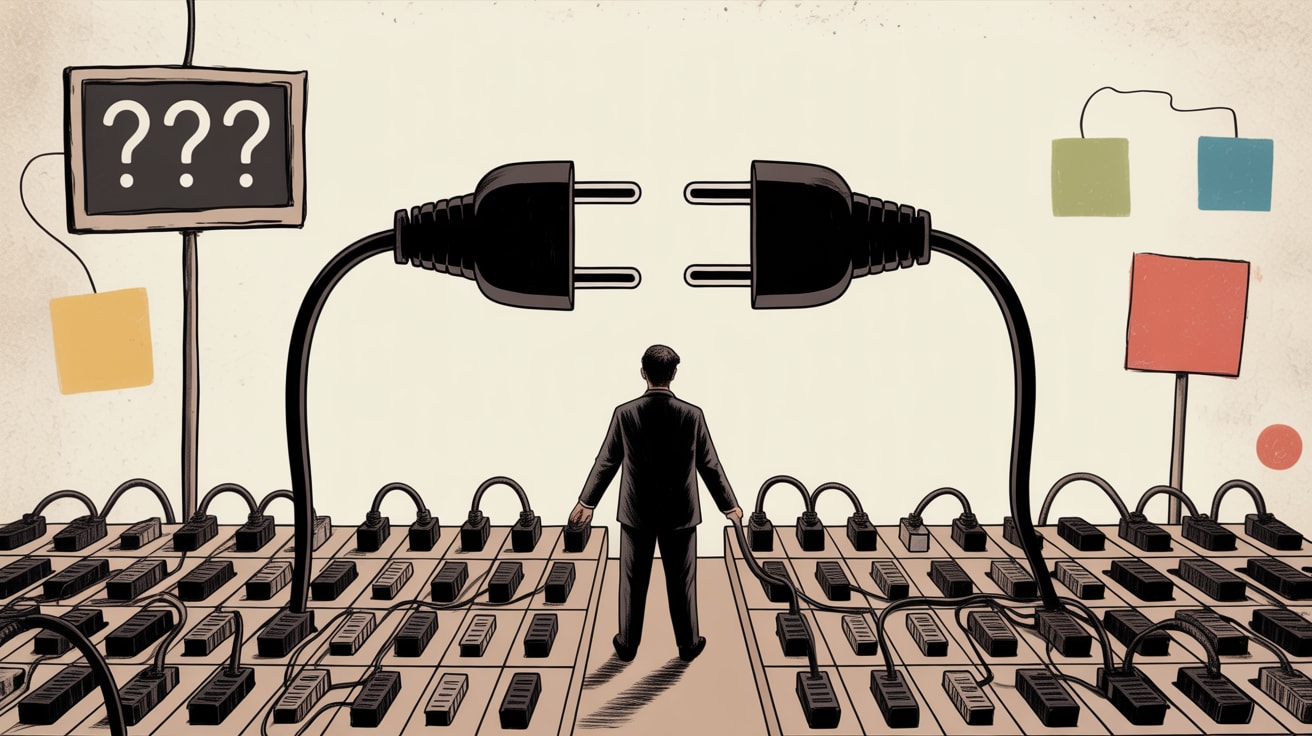
LLM visibility audits reveal the same data architecture flaws that break CEP frameworks. Here's what marketers in Southeast Asia need to fix first.
Brands across Southeast Asia spent the last two years building AI capabilities on top of data infrastructure that was never designed for real-time, context-aware anything. Now the invoice is arriving — and it looks like an LLM that doesn’t know you exist, or worse, gets you subtly wrong.
Monte Carlo’s Ashley Rothrock captures the dissonance well: the company built a data observability category from scratch and could see the scoreboard clearly. When they tried to build the next one, the scoreboard had gone dark. No signal. No feedback loop. The AI models that now shape brand perception were trained on data they couldn’t control or even see. That’s not a PR problem — it’s a data architecture problem dressed in AI clothing.
Why LLM Visibility Failures Start Upstream
LLMs don’t hallucinate your brand out of malice. They hallucinate because the structured, attributable, consistently formatted information about your brand either doesn’t exist in the training corpus or is buried under contradictory signals. Monte Carlo’s audit methodology — tracking how often and how accurately LLMs surface a brand across category-relevant queries — is revealing exactly this. Brands that defined their categories through clear, consistent, public-facing content architectures perform measurably better in LLM retrieval than those who relied on paid media and closed-ecosystem engagement.
For Southeast Asian brands whose digital presence is heavily concentrated on Shopee, Lazada, or LINE — platforms with limited crawlability and proprietary content structures — this is an acute vulnerability. Your brand narrative may be rich inside the platform, invisible outside it.
The Multi-Document Problem Is Your CRM Problem
Angela Shi’s framing from Towards Data Science hits close to home for anyone who’s tried to build a unified customer profile across a regional marketing stack: treat a folder of unrelated documents as one long document with a nested outline, and suddenly retrieval becomes tractable. The insight is architectural — impose structure where none was designed.
This is precisely the challenge inside most customer engagement platforms operating across Southeast Asia. A customer’s interaction history across a Grab super-app touchpoint, a LINE OA conversation, a Shopee product review, and a brand’s own CRM record doesn’t share fields. There’s no natural index. The brands that are winning at real-time personalisation have done the unglamorous work of creating that nested outline manually — mapping every data source to a canonical customer schema, even when the source data is messy and asynchronous. Without it, your CEP is pattern-matching against noise.
Batch-and-Blast Is a Symptom, Not the Disease
The reason most engagement platforms default to batch-and-blast isn’t laziness — it’s that real-time, context-aware triggers require clean, low-latency data pipelines that most organisations simply don’t have. The IRS contact centre modernisation contract awarded to TTEC — a $21 million, one-year engagement to upgrade infrastructure supporting one of the highest-volume contact environments in the US — is instructive here. Even a government agency with unlimited compliance pressure and operational scale recognised that the contact layer is only as smart as the infrastructure beneath it.
For brand marketing teams in the region, the implication is direct: investing in a sophisticated CEP or AI-powered engagement tool before the data plumbing is sorted is like fitting a performance exhaust to a car with a cracked engine block. The noise changes. The speed doesn’t.
Implementation-wise, this means prioritising three things before any CEP activation: a unified identity resolution layer (not just email-based), event stream standardisation across all customer touchpoints, and a data observability practice that catches pipeline failures before they corrupt personalisation logic. None of these are exciting. All of them are prerequisites.
Making Your Brand Legible to Both Humans and Machines
The LLM visibility audit approach Monte Carlo describes — systematically querying AI models for brand and category mentions, then tracing gaps back to content and data source decisions — is a discipline that marketing and data teams need to run in parallel, not sequence. In markets like Thailand, Indonesia, and Vietnam, where search behaviour is increasingly mediated by AI assistants and voice interfaces, brand legibility to machines is becoming as strategically important as brand legibility to humans.
The fix isn’t to flood the internet with more content. It’s to ensure that your owned content — product documentation, case studies, thought leadership, customer success stories — is structured, attributed, and publicly accessible in formats that both search crawlers and LLM training pipelines can parse. For multilingual markets, this compounds: a brand with strong Bahasa Indonesia content but thin English-language structured data will have asymmetric LLM visibility across the region. That’s a content architecture decision, and it needs to be made deliberately.
Key Takeaways
- Audit your brand’s LLM visibility before assuming AI tools will represent you accurately — the gaps trace back to structural data and content decisions, not model quality.
- Treat multi-source customer data like a document corpus without shared fields: impose a canonical schema before activating any real-time CEP logic.
- In Southeast Asia’s platform-heavy ecosystems, invest in public-facing, structured content to ensure brand legibility outside walled gardens.
The uncomfortable question sitting under all of this: if your brand’s story can’t be reliably retrieved by a language model trained on public data, what does that say about the coherence of your content strategy — and how much of what you think you know about your own brand’s presence is actually visible to anyone outside your own dashboards?
At grzzly, we work with marketing and data teams across Southeast Asia to design CEP frameworks that are actually grounded in the data architecture reality — not the idealised version. If your engagement platform is underdelivering, the answer is usually upstream from the platform itself. Let’s talk
Sources
Written by
Brooding GrizzlyDesigning CEP frameworks that move beyond batch-and-blast into real-time, context-aware engagement — across channels, devices, and the messiness of actual human behaviour.