
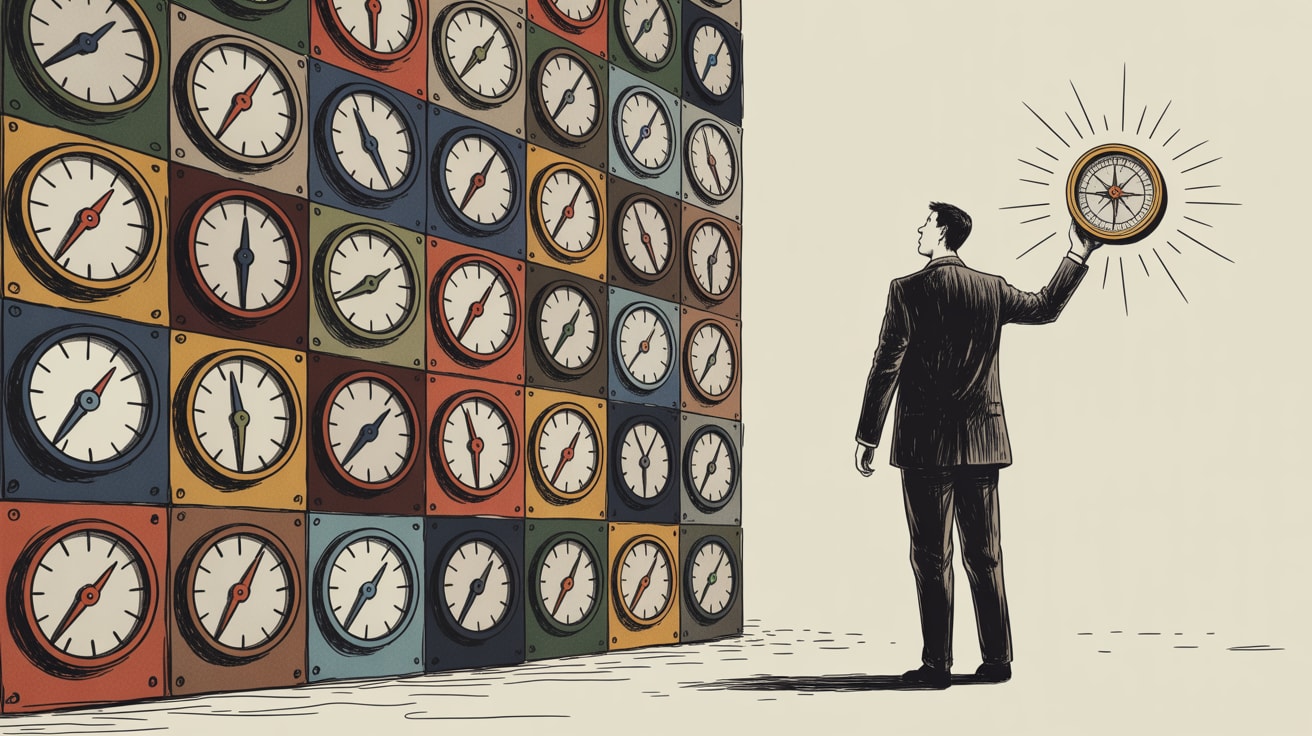
Most marketing teams trust their data more than they should. Here's how statistical traps and data silos quietly sabotage customer engagement strategy.
The average marketing team doesn’t have a data shortage. It has a data comprehension problem dressed up as a data shortage.
Tealium’s survey of over 650 marketing and IT professionals found that while most leaders recognise customer data as a strategic asset, converting it into real-time action remains the critical gap. That gap isn’t usually a technology problem. It’s a statistical and interpretive one — and it compounds quietly, buried inside dashboards that everyone trusts and almost nobody interrogates.
The Traps Already Living Inside Your Reports
Sara Metwalli’s analysis in Towards Data Science catalogues statistical errors that most practitioners recognise in theory and repeat in practice. Survivorship bias is endemic in campaign reporting — you’re measuring the customers who converted, not the larger population who saw the same message and left. Confusing correlation with causation is almost a rite of passage in growth marketing: your push notification sequence coincides with a spike in purchases, so you double the frequency, and then churn quietly accelerates.
For customer engagement teams, the more dangerous traps are subtler. Simpson’s Paradox — where a trend that appears in aggregated data reverses when you segment it — is a particular risk in Southeast Asian markets with genuinely heterogeneous audiences. A campaign that looks positive at the regional level can be actively damaging your Manila cohort while your Singapore cohort carries the numbers. If your CEP framework is optimising on blended metrics, it’s making decisions on a fiction.
Data Maturity Is the Prerequisite, Not the Reward
Here’s the uncomfortable sequence most organisations get backwards: they invest in activation technology first, then discover the data feeding it is fragmented, inconsistently defined, or just wrong. Tealium’s maturity assessment surfaces exactly this — organisations at early maturity stages are running sophisticated tools on top of siloed, unresolved data architecture.
In practice, this means personalisation engines that confidently serve the wrong content, journey orchestration that triggers on stale signals, and attribution models that reward the wrong channels with budget. The technology works exactly as designed. The inputs are the problem.
Data maturity in this context means three things: unified customer identity across channels (not just stitched-together IDs, but resolved profiles that hold across a Shopee session, a LINE message, and an in-store visit), consistent event taxonomy so that “add to cart” means the same thing in every system, and governance that prevents individual teams from redefining metrics to suit their own reporting cycles.
When You Activate on Bad Interpretations, You Scale the Damage
This is where the statistical traps become expensive. A batch-and-blast operation sends a bad message to a million people once. A real-time CEP framework, optimising continuously on flawed signals, can entrench those errors into every future interaction. The model learns the wrong thing — and it learns it confidently.
Fine-tuning AI models on proprietary customer data (a legitimate strategy for improving relevance) amplifies this risk. Monte Carlo’s analysis of fine-tuning versus full model training makes the tradeoff explicit: fine-tuning is cheaper and faster, but it inherits the biases and gaps of whatever data you feed it. If your training set overrepresents high-value customers, your fine-tuned model will systematically underserve the mid-tier segments that often represent the largest revenue opportunity in Southeast Asian markets — where a much larger proportion of the addressable audience sits in the RM150–500 monthly spend range than brand managers typically acknowledge.
Phonely’s Alma, trained on 10 million real phone conversations, demonstrates what domain-specific training can achieve — 63% faster response times and materially better call quality scores than generic models. The principle applies directly to engagement AI: specificity of training data matters more than scale of training data. But specificity requires that your underlying data is clean, representative, and honestly labelled.
Building the Framework That Doesn’t Lie to Itself
The path forward is less about adopting new tools and more about installing honest feedback loops into the ones you already have.
Start with statistical hygiene at the reporting layer. Define your control groups properly — holdout groups for every significant journey trigger, not just major campaigns. Segment your metrics by cohort before drawing conclusions at the aggregate level. When a metric moves, ask what else changed in that period before attributing causation.
Then address the data maturity gap structurally. For most mid-to-large organisations in Southeast Asia, the priority is identity resolution — getting a single, trustworthy view of a customer across the fragmented touchpoints that define regional behaviour: LINE in Thailand, WhatsApp in Malaysia and Singapore, Zalo in Vietnam, Shopee and Lazada across the region. Without resolved identity, real-time personalisation is personalisation in name only.
Finally, build model monitoring into your CEP operations from day one. Track not just model performance metrics, but the distribution of inputs over time. Data drift — when the real-world behaviour of your customers shifts away from the conditions your models were trained on — is invisible until it’s already done damage. In markets moving as fast as Southeast Asia’s, that window can be very short.
Key Takeaways
- Segment every aggregate metric by meaningful cohorts before acting — Simpson’s Paradox is a real operational risk in heterogeneous Southeast Asian audiences, not a statistics textbook curiosity.
- Resolve customer identity across platforms before investing further in activation technology — personalisation built on unresolved data actively scales your errors.
- Install holdout groups and input distribution monitoring as standard practice in CEP operations, not as an afterthought when performance degrades.
The question worth sitting with: if your engagement platform is a confidence machine — always optimising, always certain — what mechanisms do you actually have to detect when it’s confidently wrong? Most teams don’t have a good answer. That gap is where the next wave of competitive differentiation in customer engagement will be won.
At grzzly, we work with marketing and data teams across Southeast Asia to build CEP frameworks that are honest about their own limitations — starting with data architecture that can actually support real-time, context-aware engagement rather than just promising it. If your activation strategy is outpacing your data maturity, that’s a conversation worth having. Let’s talk
Sources
Written by
Brooding GrizzlyDesigning CEP frameworks that move beyond batch-and-blast into real-time, context-aware engagement — across channels, devices, and the messiness of actual human behaviour.