
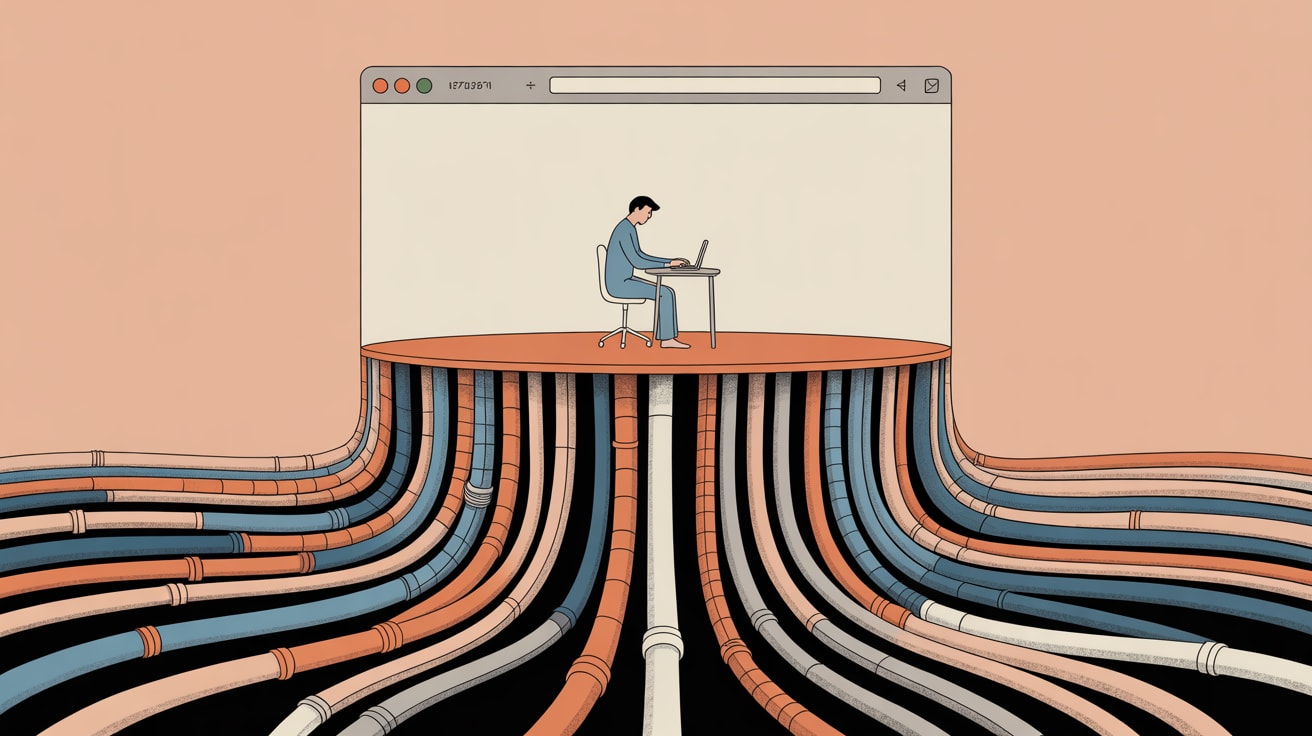
Browser-based design tools promise convenience, but the real story is in the data pipelines behind them. What UX teams in Southeast Asia need to know.
Most UX debates about browser-based design tools get stuck on the wrong question. Teams argue about feature parity with desktop software — whether Figma’s auto-layout matches Sketch, whether Canva’s export options satisfy production requirements. But the more consequential question, particularly for marketing and design teams operating at scale across Southeast Asia, is this: what happens to your data inside these tools, and do you actually know?
As someone who spends most of their time building the pipelines that turn raw platform data into decisions, I find the browser-based tool conversation fascinating — not for the UX reasons designers cite, but for what it reveals about how organisations think (or don’t think) about data sovereignty, workflow intelligence, and the hidden costs of convenience.
The Collaboration Case Is Real, But It’s Incomplete
Speckyboy’s Eric Karkovack makes a strong case for browser-based design apps: real-time collaboration, zero version-control chaos, accessible from any device on any OS. For distributed teams across Manila, Jakarta, and Bangkok — often working across patchy mobile connections — the appeal is obvious. There’s no arguing with the workflow efficiency gains when a Bangkok-based creative director can review and annotate a Kuala Lumpur designer’s work in real time without emailing a 200MB file.
But here’s what that efficiency narrative quietly skips: your design assets, user research files, prototype interactions, and client briefs now live on someone else’s infrastructure. For brands operating in markets with evolving data localisation requirements — Indonesia’s Personal Data Protection Law being the obvious recent example — that’s not a UX decision, it’s a compliance posture. The collaboration benefit is genuine. The governance question is real too.
Where Desktop Tools Still Hold the Line
Karkovack identifies three areas where desktop tools retain a meaningful edge: performance on large, complex files; offline reliability; and privacy for sensitive work. From a data architecture perspective, I’d add a fourth: auditability.
When design work happens inside a browser-based SaaS tool, the activity log, version history, and asset metadata all sit in that vendor’s data model — not yours. For enterprise brands running design systems across dozens of markets and hundreds of SKUs (think a regional FMCG brand managing Shopee storefronts in six countries), the inability to pipe design workflow data into your own warehouse is a genuine intelligence gap. You can’t answer questions like: which design iterations correlate with higher conversion on Lazada product pages? Which component variations were tested before the campaign that underperformed?
Desktop-native workflows, with proper asset management and version control (Git-based or otherwise), keep that data inside your own systems — queryable, joinable to business outcomes, actually useful.
The Pricing Signal Hidden in Plain Sight
UX Collective’s Hiroshi Sato wrote recently about the psychology of pricing — specifically, how the way we frame price reveals deeper assumptions about value. It’s a piece ostensibly about saying no to discount requests from friends, but the underlying insight applies directly to the browser-based tool debate: we systematically undervalue things we don’t pay for directly, and overvalue things that come with a monthly invoice.
Design teams often treat browser-based tools as essentially free infrastructure — the subscription is cheap, the onboarding is frictionless, and the switching cost feels low. But the actual cost is denominated in data lock-in, vendor dependency, and the slow erosion of your ability to build proprietary intelligence about your own creative process. That’s a cost that doesn’t show up in the SaaS line item. It shows up eighteen months later when you’re trying to understand why your design refresh moved the needle in Vietnam but flatlined in Thailand, and you have no structured data to interrogate.
Building a Tool Stack That Generates Intelligence
The practical question for design and marketing leads isn’t “browser or desktop?” — it’s “what data does this tool generate, who owns it, and can I use it?” Here’s a framework that works in practice:
Map your data outputs before you commit to a tool. Before standardising on any design platform, document what structured data it produces: version history, component usage, collaboration events, export logs. Ask whether the vendor provides API access or data export in a usable format. Figma’s REST API, for instance, allows you to extract file metadata and component analytics — useful if you’re willing to build the pipeline to consume it.
Separate collaboration layer from source of truth. Use browser-based tools for what they’re genuinely good at — real-time review cycles, stakeholder feedback, rapid ideation. But maintain a desktop-anchored or self-hosted source of truth for production assets and design system components. This isn’t about being precious; it’s about knowing where the canonical data lives.
Instrument your design workflow the same way you instrument your product. If you’re running A/B tests on landing pages but have no structured record of which design variants were considered and discarded, you’re missing half the dataset. Even a lightweight metadata schema — tagging design files with campaign IDs, target markets, and test hypotheses — creates joinable data that can later connect design decisions to business outcomes.
For Southeast Asian teams managing multi-platform campaigns across Shopee, Lazada, and LINE simultaneously, this kind of structured design intelligence isn’t a luxury. It’s what separates teams that learn from campaigns from teams that just run them.
The forward-looking question worth sitting with: As AI-assisted design tools begin generating UI variations autonomously, the brands that have already built clean pipelines connecting design decisions to business outcomes will be able to train those tools on proprietary signal. Everyone else will be training on generic benchmarks. Which camp is your organisation building toward?
At grzzly, we work with marketing and growth teams across Southeast Asia who are trying to make sense of exactly this intersection — design workflows, data infrastructure, and the business intelligence that should flow between them. If your team is rethinking its tool stack or trying to build cleaner feedback loops between creative decisions and commercial outcomes, we’d enjoy the conversation. Let’s talk
Sources
Written by
Chunky GrizzlyDesigning the foundational plumbing — data warehouses, lakehouse models, and ETL pipelines — that separates organisations with genuine intelligence from those drowning in dashboards.