
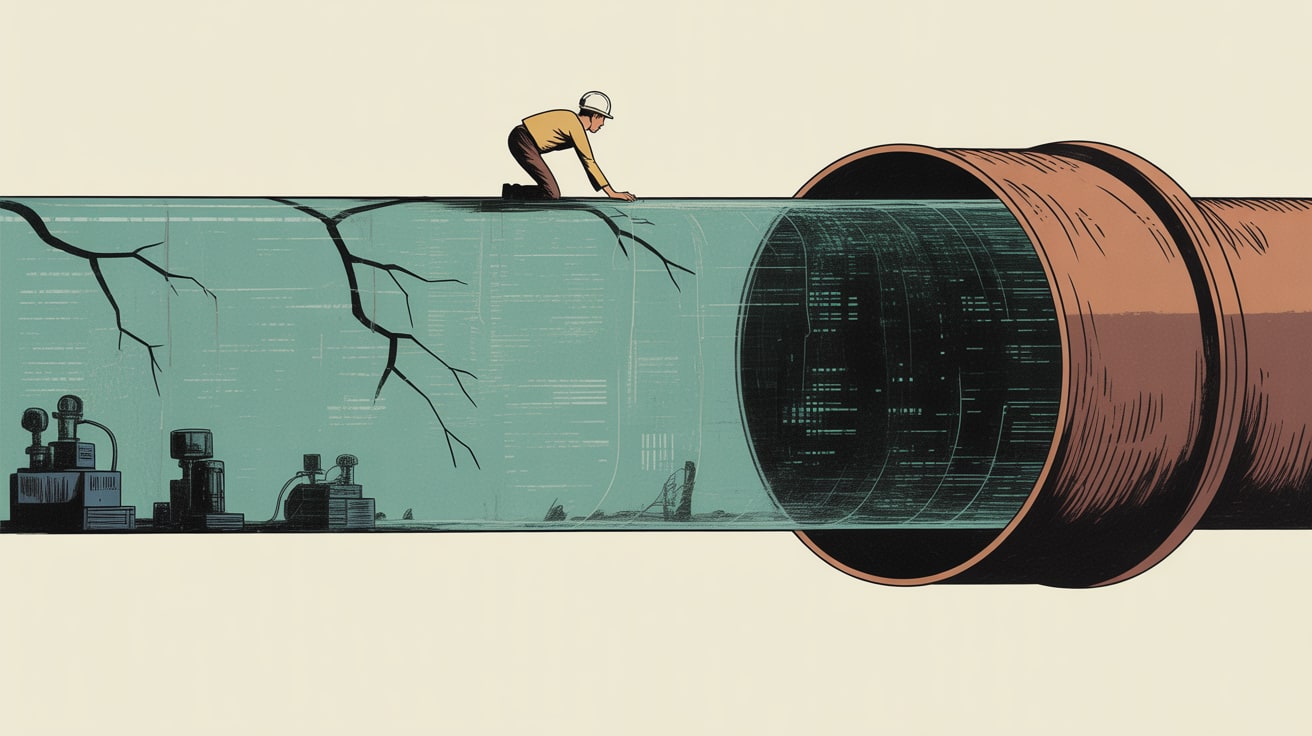
AI scaling is exposing governance gaps brands can't ignore. Here's what breaks first in your data stack — and how to build trust before it costs you.
Brands across Southeast Asia spent the last two years racing to deploy AI across their marketing stacks. The models scaled. The trust didn’t.
According to dbt Labs, the first thing that breaks when AI scales isn’t the model — it’s the data underneath it. Specifically: lineage gaps, undocumented transformations, and consent assumptions that were always too thin to bear weight. That’s not a technology problem. It’s a governance debt that compounded quietly until an AI system tried to act on it at speed.
The Governance Debt Nobody Budgeted For
Most data teams inherit pipelines built during a period when “collect everything” felt like prudent hedging. The dbt Labs analysis is blunt about what happens next: as AI systems ingest and act on that data at scale, the ambiguity that a human analyst would pause over becomes an automated decision that nobody notices until it’s wrong — or until a regulator asks questions.
In Southeast Asia, this risk is acute. Thailand’s PDPA, Indonesia’s UU PDP, and Singapore’s PDPA amendments all carry enforcement teeth, and they share a common expectation: that organisations can demonstrate why they hold data and what they consented to do with it. A personalisation model trained on six years of behavioural data, half of which predates a consent framework refresh, is not compliant by default. It’s a liability dressed in a dashboard.
The fix isn’t to slow down AI adoption. It’s to treat data documentation as a prerequisite, not an afterthought. Teams that implement data contracts — explicit, versioned agreements between data producers and consumers — find that governance becomes a feature of the stack, not a tax on it.
Personalisation That Earns Its Keep
Tealium’s account of personalising their own website using their own Customer Data Platform is instructive precisely because it’s unglamorous. Their team didn’t start with the model — they started with the data layer: unified profiles, consent state included as a first-class attribute, and clear rules about which signals could activate which experiences.
The outcome was measurable. By treating consent state as an activation signal rather than a compliance checkbox, they could serve genuinely differentiated experiences to visitors who had shared more context — and do so without the legal exposure that comes from assuming equivalence between a cookie acceptance and a behavioural inference license.
For brands running on Shopee, Lazada, or LINE ecosystems in Southeast Asia, this architecture matters differently than it does in a Western context. Platform data is often siloed, consent flows are platform-controlled, and first-party signals on owned properties are correspondingly more valuable. A visitor who arrives on your direct site and consents meaningfully is worth more in data terms than ten platform impressions — if you’ve built the infrastructure to recognise and act on that distinction.
SQL’s Underused Role in Trust Infrastructure
Here’s where data engineering and consent strategy converge in a way that rarely gets discussed in marketing circles: recursive CTEs. Thomas Reid’s analysis in Towards Data Science makes the case that SQL’s graph traversal capabilities — the ability to trace hierarchies, detect cycles, and calculate degrees of separation — are underused outside of engineering teams.
For consent and governance practitioners, the implication is direct. Data lineage is a graph problem. Understanding whether a derived audience segment is three transformations away from a consented first-party signal — or whether it’s crossed a boundary into inferred territory — requires the same traversal logic that a graph database would apply. Most BI teams already have the tool. They’re just not applying it to the governance question.
Practically: if your data team can write a recursive CTE to map product category hierarchies for merchandising, they can write one to trace a personalisation signal back to its consent root. That’s not a new capability — it’s a new use case for an existing one. The ROI case to stakeholders writes itself: fewer compliance surprises, cleaner audit trails, and AI outputs that leadership can actually stand behind.
Building Trust as a Competitive Asset
The brands that will win the next phase of AI-enabled marketing in Southeast Asia aren’t necessarily the ones with the most data. They’re the ones whose data their systems — and their customers — can trust.
Dbt Labs frames this as an infrastructure problem. Tealium frames it as a product problem. Both are right, and neither framing fully captures the strategic opportunity: brands that build consent into their data architecture from the collection layer upward create a durable first-party asset that compounds in value as third-party signals erode. That’s not compliance overhead. That’s a moat.
The implementation path is sequential, not simultaneous. Start with data contracts on your highest-stakes personalisation inputs. Layer in consent state as an activation attribute rather than a filter. Use your existing SQL capabilities to trace lineage before your next model deployment. None of this requires a platform overhaul — it requires the organisational decision that governance is a prerequisite, not a clean-up task.
Key Takeaways
- Treat consent state as a first-class data attribute that activates (or constrains) personalisation logic, not a checkbox appended at the compliance stage.
- Audit your AI training inputs for lineage before deployment — recursive CTE-based lineage tracing is a tractable approach using tools most data teams already have.
- In Southeast Asian markets, owned first-party signals from consented users carry disproportionate value relative to platform-mediated behavioural data; build infrastructure that reflects this asymmetry.
The AI trust gap will close — but probably not through better models. It will close through teams that decide, deliberately, to treat governance as a design constraint rather than a retrofit. The question worth sitting with: if your best-performing personalisation campaign had to demonstrate its consent lineage to a regulator tomorrow, how far down the stack would you get before the trail went cold?
At grzzly, we help Southeast Asian brands build first-party data programmes where consent architecture and activation strategy are designed together from day one — not reconciled after the fact. If your team is scaling AI-driven personalisation and wants the governance infrastructure to match, let’s talk.
Sources
Written by
Lavender GrizzlyTurning privacy constraints into competitive advantage. Builds first-party data programmes that are compliant by design, valuable by intent, and trusted by the people whose data they hold.